文章背景与核心概要
本文探讨了人类编写的文本与人工智能生成的内容是否能够被区分这一长期争论。作者指出,虽然单个 AI 生成的句子在语法和统计学上可以模仿人类,但大语言模型(LLM)天生的“准确定性”(quasi-deterministic nature)在面对海量重复提示时,会暴露出极具辨识度的程式化特征、视觉聚类以及风格同质化现象。
通过剖析亚马逊平台上充斥的大量 AI 生成儿童非虚构类图书(如带有雷同恐龙封面的“10 万个为什么”系列),文章揭示了自动化内容泛滥背后的指纹特征。当生产内容的成本远低于与之互动或审查的成本时,依靠直觉去识别这种高密度的“AI 垃圾内容(AI slop)”在今天的互联网生态中显得尤为重要。
AI 的十万个为什么
我和同行技术人员经常会争论一个令人头疼的问题:你究竟能不能区分出人类写的文本和人工智能生成的文本?
One of the most painful arguments I keep having with fellow techies is the question of whether you can distinguish between human-written and AI-generated text.
他们的怀疑是有道理的:从核心上看,大语言模型是关于人类说话方式的顶尖统计模型。如果真是这样,在任何统计检验下,模型输出的内容几乎在定义上就应该与人类语言无法区分。
Their skepticism is rooted in reason: at their core, LLMs are state-of-the-art statistical models of how humans talk. If so, the output from the model should be almost by definition indistinguishable from human language under any statistical test.
我不认为这种争论每次都是出于善意;至少有一些争论是由那些希望为自己暗中滥用这项技术保留否认空间的人挑起的。但如果你真诚地坚信这一点,我向你展示以下拼图:
I don’t think this is always argued in good faith; at least some of the debates are started by folks who wish to maintain deniability for their own underhanded use of the tech. But if you sincerely hold this belief, I present you the following collage:
[](https://substackcdn.com/image/fetch/\)s_!qskh!,f_auto,q_auto:good,fl_progressive:steep/https%3A%2F%2Fsubstack-post-media.s3.amazonaws.com%2Fpublic%2Fimages%2F6d0ea4c6-54b8-4dff-ae4f-c0a2409360b5_7000x7000.jpeg)
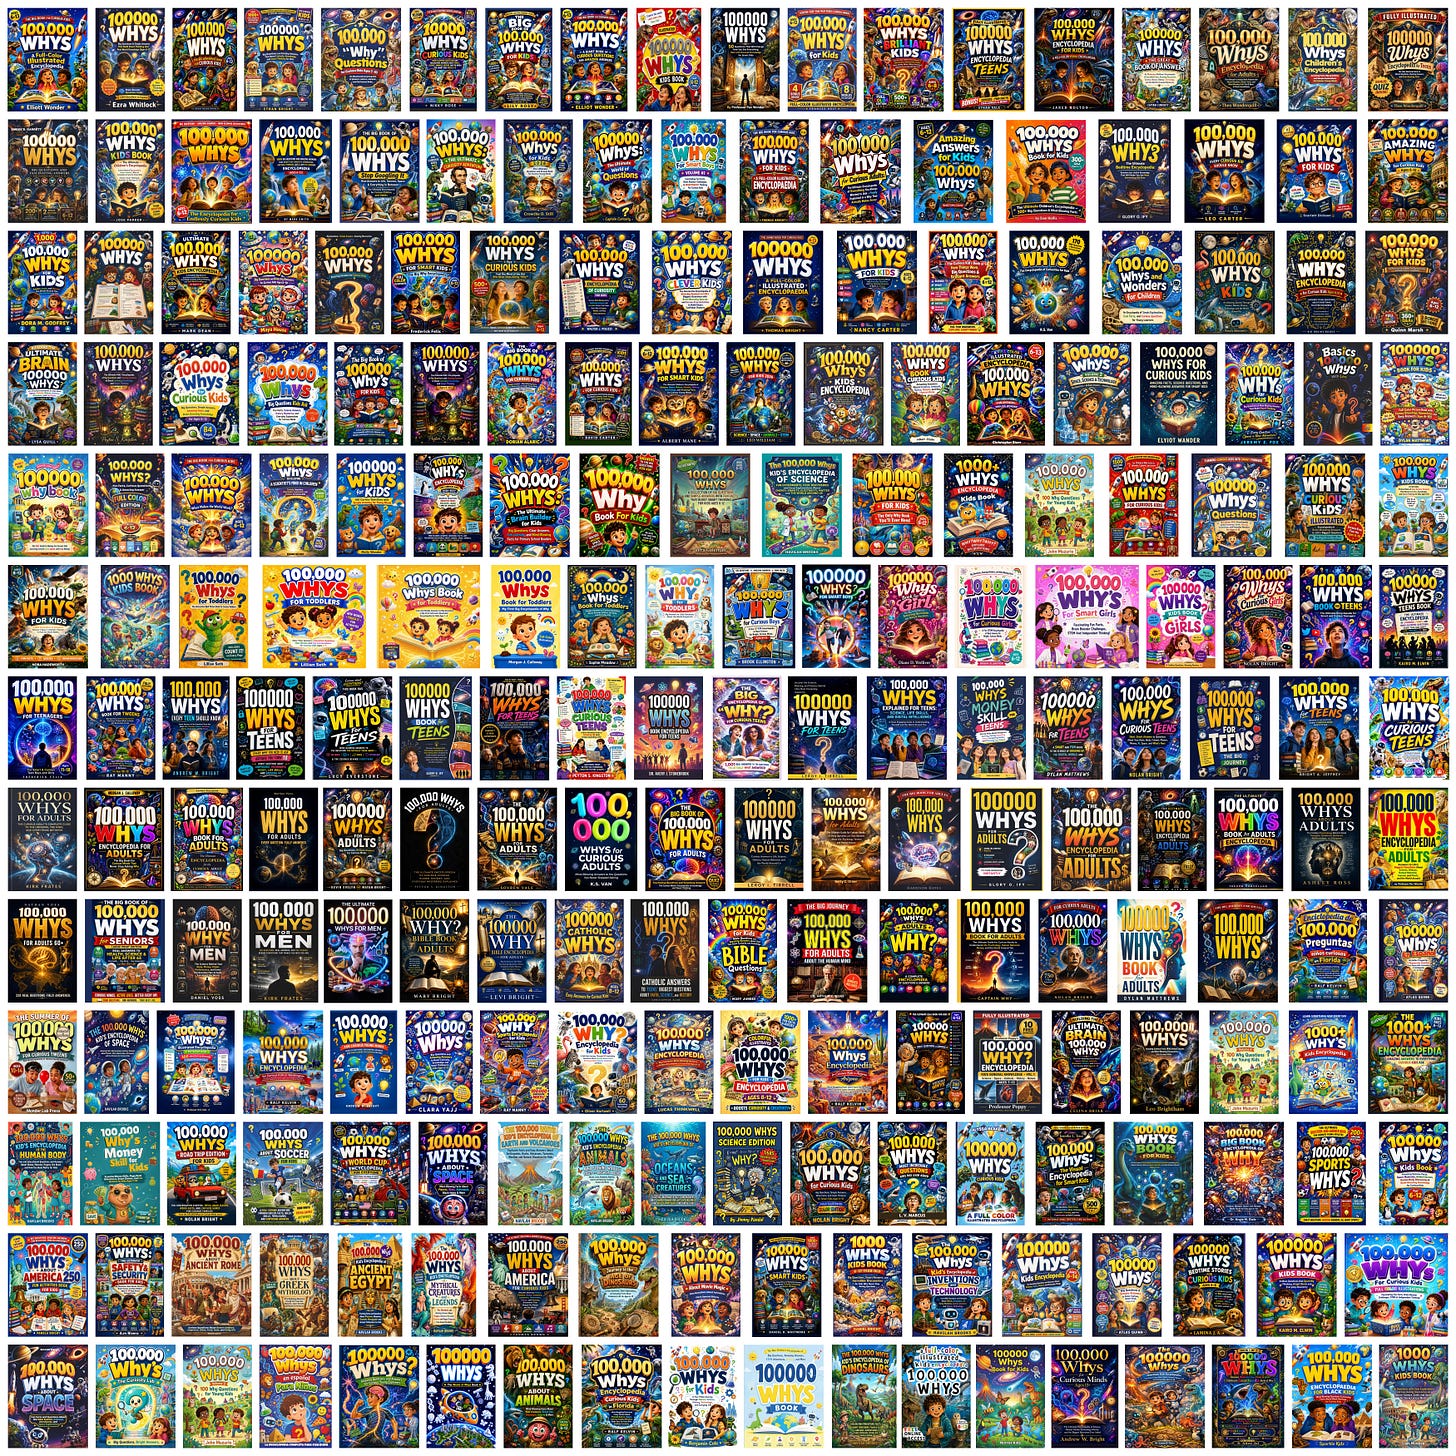
这张图片展示了大约 220 本亚马逊图书的封面,这些封面是在网站上搜索“100000 whys”(链接)时出现的。其中一些书籍还是儿童文学类别的畅销书。你可以在这里查看可缩放的高分辨率版本。

The image shows about 220 Amazon book covers that appear if you search the site for “100000 whys” (link). Some of these books are category bestsellers in children’s literature. You can view a zoomable, full-resolution version here.
这些书名或封面并没有什么非人类的地方。与此同时,我大概不需要说服你,你现在正盯着的是目前充斥在亚马逊许多非小说类图书类别中的最纯粹的 AI 垃圾内容。更具体地说,这是这些工具具有准确定性的产物:如果有上百个“作者”给他们最喜欢的 AI 工具输入相似的提示词——比如“为儿童生成一本参考书”——在 80% 的情况下,模型可能会产生功能上完全相同的输出。
There’s nothing inhuman about any of these titles or covers. At the same time, I probably don’t need to convince you that you’re staring at the purest form of AI slop that now fills up many nonfiction book categories on Amazon. More specifically, it’s the artifact of the tools being quasi-deterministic: if a hundred “authors” give their favorite AI tool a similar prompt — say, “generate a reference book for children” — the model will produce functionally identical output perhaps 80% of the time.
拼图中的相似之处远不止书名的选择:例如,前两行中有三十多个封面左侧都有一只咆哮的霸王龙(T-Rex):
The similarities in the collage go far beyond the choice of titles: for example, more than thirty covers in the two top rows feature a roaring T-Rex on the left:
[](https://substackcdn.com/image/fetch/\)s_!pur0!,f_auto,q_auto:good,fl_progressive:steep/https%3A%2F%2Fsubstack-post-media.s3.amazonaws.com%2Fpublic%2Fimages%2Fed237fb5-ffca-43cb-8d33-a23d09f3237f_2000x1137.jpeg)
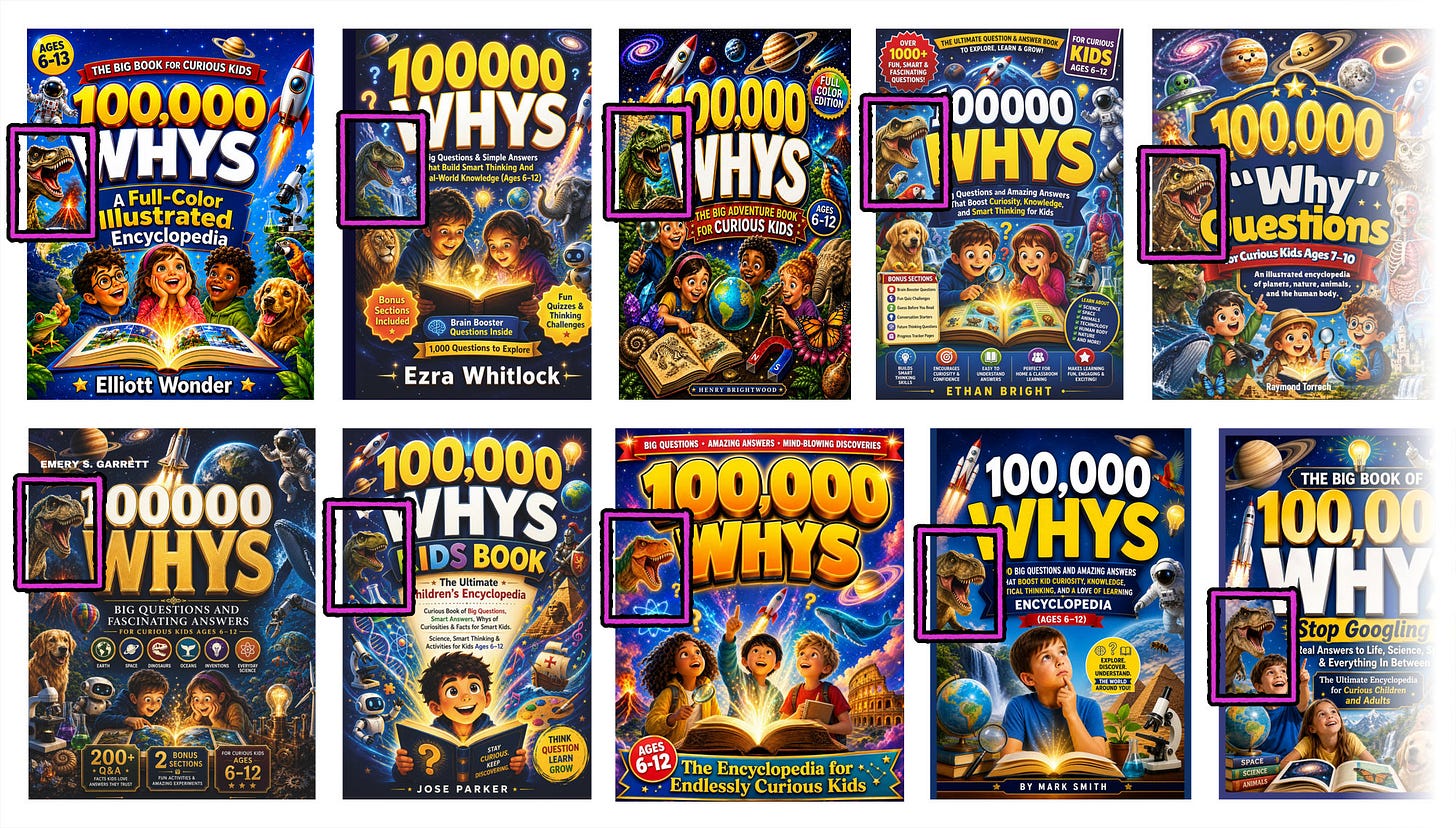
数据中还有许多其他的视觉聚类。寻找发光的书本、红白相间的卡通火箭、金毛寻回犬、狮子、蓝眼睛的机器人等等。这些相似性甚至延伸到了作者的名字:Ethan Bright、Nolan Bright、Pamela Bright、Daniel Bright、Thomas Bright、Andrew W. Bright、Mayan Bright、Mary Bright、Levi Bright——布莱特(Bright)家族一定是个庞大且极其富有才华的家族。
There are many other visual clusters in the data, too. Look for glowing books, red-and-white cartoon rockets, golden retrievers, lions, blue-eyed robots, and so forth. The similarities extend even to author names: Ethan Bright, Nolan Bright, Pamela Bright, Daniel Bright, Thomas Bright, Andrew W. Bright, Mayan Bright, Mary Bright, Levi Bright — the Brights must be a big and exceptionally talented family.
这正是 LLM 写作的独特之处:并不是说模型的个人习惯用语与我们不同,而是它们在回应几乎任何普通提示时,都会诉诸于相同且复杂的习惯用语组合。这是一个模糊的信号,所以当你的实习生说“不是这个——是那个”时,你不应该解雇他们。但在更随意的场合下,相信你的直觉是没有问题的。事实上,这些直觉变得越来越重要,因为如果生产内容的成本远低于与之互动的成本,传统的网络互动模型就会彻底崩溃。
This is precisely what makes LLM writing distinctive: it’s not that the models’ individual mannerisms are different from ours. It’s that they resort to the same, complex set of mannerisms in response to almost any normal prompt. This is a fuzzy signal, so you shouldn’t fire your intern when they say “it’s not this — it’s that”. But in more casual settings, it’s OK to trust your gut. In fact, these instincts are becoming increasingly important because traditional models of online interactions fall apart if it takes much less effort to produce content than to engage with it.
附言:如果你正在使用 LLM 来自动化博客或社交媒体评论:是的,这项技术很惊艳,但你的出版物很可能会被改名为《十万个为什么》。
PS. If you’re using an LLM to automate blogging or social media commentary: yes, the tech is amazing, but chances are, your publication could be renamed to “100,000 Whys”.
想要阅读后续文章,请点击这里:
For a followup article, click here:
如果你喜欢那些超乎我们理解的恐怖事物,请订阅我们。
And if you like horrors beyond our comprehension, please subscribe.